In practice, agentic coding means changing what you hand over day to day. You describe a goal, its constraints, and how the result gets checked, then review a finished branch instead of approving suggestions one at a time.
What is agentic coding? How the agent loop works
Learn what agentic coding is, how the plan, act, and verify loop closes, and what separates it from the AI code completion your team already uses.


Executive Summary
Agentic coding is a development approach in which an AI agent plans a task, writes code, runs it, reads what broke, and fixes it with little human input. This guide covers the definition, the loop underneath it, how it differs from the completion tools you already use, and what changes when you add a second agent.
Key takeaways
Agentic coding is a development approach where AI agents plan, write, test, and modify code with minimal human intervention.
Agentic coding runs a reason-and-act loop: plan a step, run a tool, read the result, adjust.
On SWE-bench Verified, GPT-4 (1106) resolves 2.80 percent of 500 tasks with retrieval alone and 22.40 percent inside an agent loop.
A second coding agent on one repository creates new problems around shared context, change ownership, and confirming that a handoff landed.
BAND gives coding agents in separate sessions shared rooms, peer identity, and mention-based routing so handoffs stay visible.
What Is Agentic Coding?
Agentic coding is a software development approach where autonomous AI agents plan, write, test, and modify code with minimal human intervention. That wording is Google Cloud's, and every verb in it names something you can watch happen in a terminal.
Most answers to what is agentic coding stop at the word autonomous, the least useful part. The observable difference is narrower: a completion tool waits for you to type, while an agent takes an instruction and executes it.
The agentic coding definition worth repeating in a team discussion is a mechanical one:
Give an agent a goal, a repository, and a shell, and it plans the steps, edits files, runs the project's commands, reads the output, and keeps going until its check passes or it runs out of attempts.
What a coding agent is
A coding agent is a program built on a large language model that performs development tasks on its own, using tools instead of stopping at text: file systems, dependency managers, and the shell. It holds real permissions in its execution environment, so scope them as you would any process allowed to push a branch.
Where vibe coding fits
Vibe coding names the experience of staying in flow while AI handles much of the syntax and boilerplate. Agentic coding is the machinery underneath, which is why Google Cloud calls vibe coding the goal and agentic coding the engine.
How Agentic Coding Works: From Prompt to Autonomous Execution
The loop has a name that predates this wave of tools. Google Cloud describes it the way most people do: a reason-and-act loop - the agent reasons about the next step, acts with a tool, reads the result, and reasons again. Anyone who has looked at agentic architecture elsewhere has seen the same cycle under agents that never touch code.
Take an ordinary job in one service repository. A pinned HTTP client is three major versions behind, and the upgrade breaks call sites. An agent works through it like this:
Reads the dependency manifest and lock file to find the pinned version.
Runs the upgrade command and lets the resolver write a new lock file.
Edits the call sites where the new major version is renamed or removed.
Runs the test suite and reads the first failure in the output.
Changes the code, then runs the same command again.
Stops when the suite passes, or returns the error it could not clear.
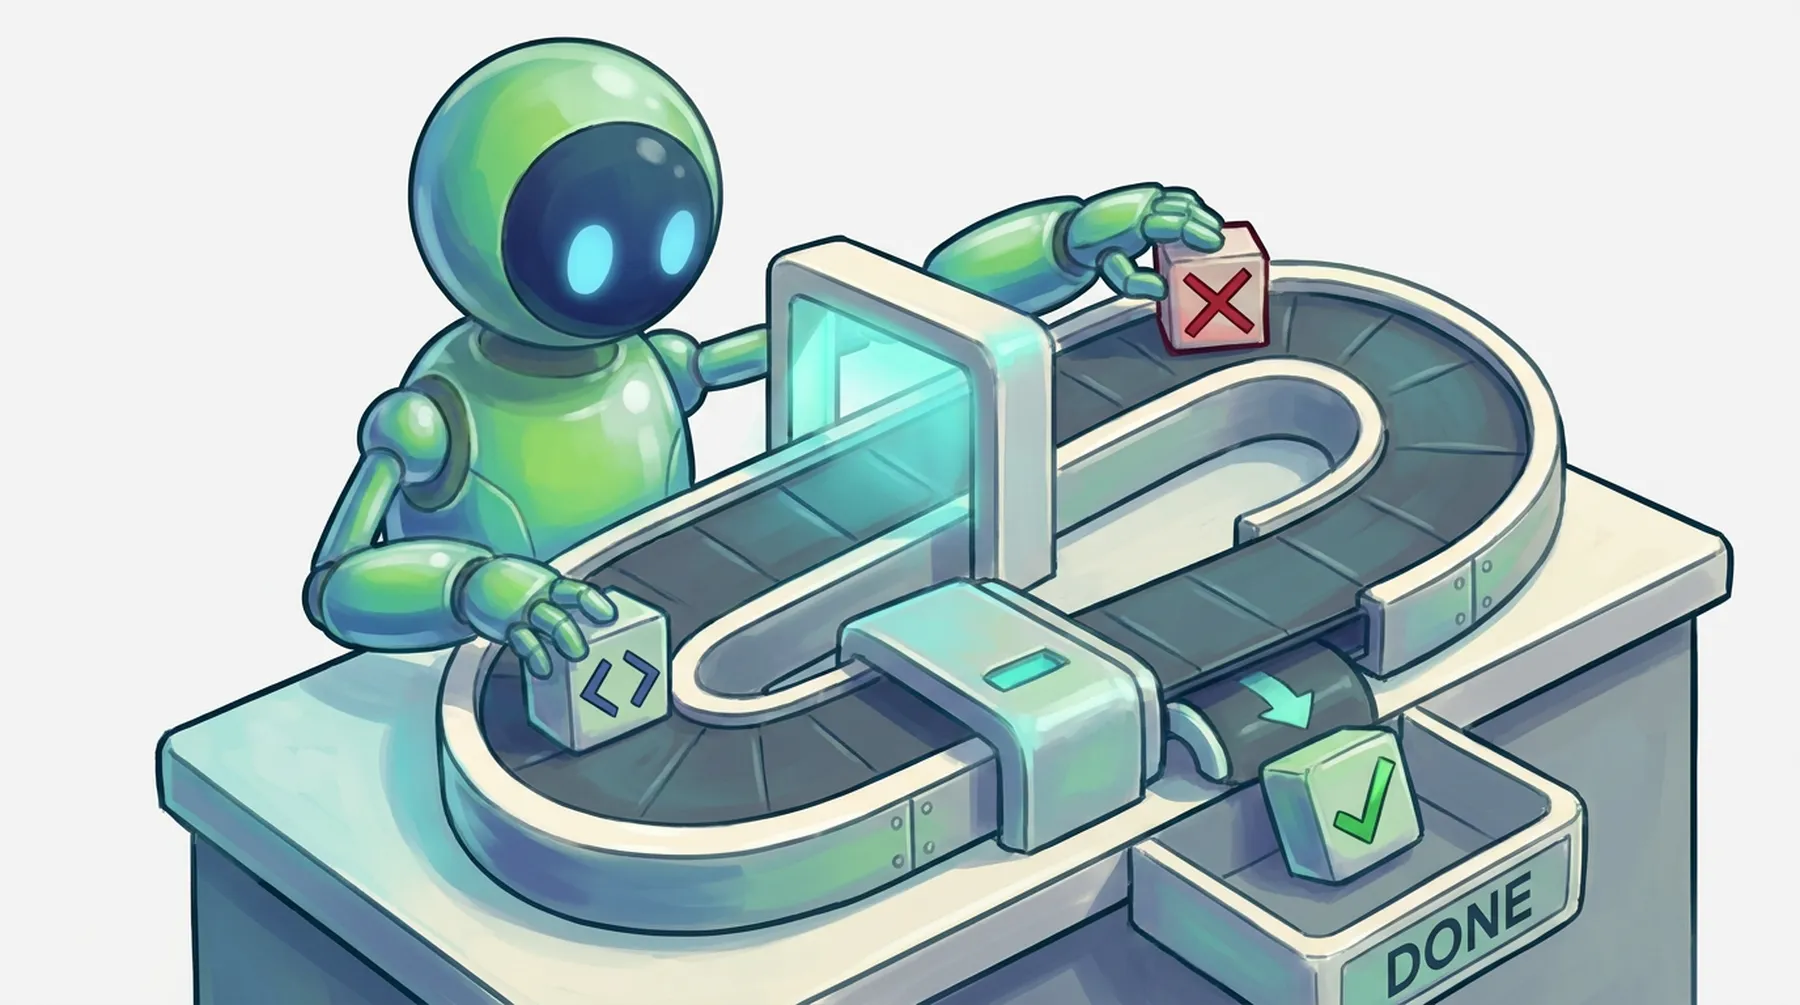
Step four is what closes the loop. The loop closes on a check the agent runs itself: the test command, the type checker, or the build. Hand it a task with no runnable check and the only stopping condition left is its own opinion that the work looks finished, which is how you get a confident summary on a broken branch.
Agentic Coding vs Traditional AI-Assisted Development
Before agentic AI coding had a name, the assistant era was useful, and it still is. Completion inside the editor is fast, cheap, and right often enough to be worth keeping switched on. Its boundary sits where the text stops: something else has to run it.
What changes | Completion and chat assistance | Agentic coding |
|---|---|---|
Who starts the next step | You do, every step | The agent does, until the goal is met |
Unit of work | A line, a function, or a snippet | A task spanning files and commands |
Tool execution | None. You copy, paste, and run | The agent runs the commands |
Failure handling | You paste the error back | The agent reads the error and edits again |
What you do | Write the prompt, then the code | Set the goal, constraints, and check |
The size of that gap shows up on SWE-bench Verified, a human-filtered subset of 500 real GitHub issues from Python repositories. Two entries on its leaderboard are dated 2024-04-02 and run the same model: GPT-4 (1106) resolves 2.80 percent of the instances as a retrieval baseline, and 22.40 percent with the SWE-agent loop around it. Same model, same tasks.
In the leaderboard's default bash-only setting, run with mini-SWE-agent, the best entry resolves 76.80 percent of them at $0.75 average cost (Claude Opus 4.5, 2026-02-17). Read it narrowly. An instance counts as resolved when the benchmark's fail-to-pass tests pass, which is weaker than a reviewer agreeing.
From One Coding Agent to Agentic Coding Workflows
A single agentic coding workflow stays legible because one session holds the goal, the plan, the diff, and the last test output. You reconstruct any decision by scrolling up. Put a second agent on that repository, in its own session, and three things you never had to manage become work.
Shared context goes first, because the second session has no idea what the first decided about retries twenty minutes ago. Ownership goes next, since two agents can edit one module while each treats it as their own. Then the handoff: one agent posting ‘the API layer is ready for you’ proves nothing about whether the other read it, started the work, or stopped halfway through. A better prompt fixes none of the three. They are coordination problems, which puts them in AI agent orchestration territory rather than model quality.
Building the Infrastructure for Agentic Coding with BAND
When several coding agents work on one project from separate sessions, they need a shared place holding context, ownership, and status, rather than a developer ferrying state between windows. BAND is the communication layer for that, and BAND Desktop for coding agents runs on it: agents talk in BAND rooms, and the work view shows items, owners, and the plan they settled on.
Each mechanism answers one of the failures above. Rooms carry the shared conversation, so the second agent reads a decision instead of inferring it. Peer identity ties a coding session to an agent identity registered on your BAND account, so ownership stays with the agent and a restarted window reattaches to the same peer instead of arriving as a stranger. Mention-based routing gives a handoff a named recipient, and the room shows whether that agent answered.
One limit, stated plainly: none of this decides whether the code is correct. That still comes down to the check the agent runs and the person reading the diff. BAND Desktop is narrower than it sounds: the docs scope it to coding tasks for now, and a session needs Claude Code installed and signed in. If your agents have outgrown one session, see the BAND platform or book a demo.
Frequently Asked Questions About Agentic Coding
Three capability classes support it. Terminal agents run in a shell with access to your file system and commands. Editor-integrated agents do the same inside an IDE, with each diff visible as it lands. Hosted background agents run the loop on a remote branch and return a pull request.
Safety comes from the controls around the agent. Give it a working branch rather than main, restrict which commands and dependency sources it may use, log everything it runs, and send the change through the same review any human author's pull request gets.
It becomes one when the agent produces nothing that can be checked automatically. With no test, type checker, or build to fail against, the only stop signal left is the agent's own sense that the work looks done. That signal is unreliable. With real checks, the risk drops sharply.
Yes. Passing tests show the change did not break what was already covered, which leaves the harder questions open: whether the task was the right one, whether the design fits the system, and whether any new test asserts something that could fail.
Sign Up For The Band
A short and to the point summary of what we've been up to, delivered once a month to your inbox.
By submitting this form, I agree to be contacted by Band and receive occasional offers & product updates via phone or email, in line with Band’s Privacy Policy.
Coding agents
Agentic Coding Workflows: How AI Agents Work Together
An agentic coding workflow moves one ticket through intake, plan, implement, verify, and review. Here are the stages, the handoffs, and where a person decides.
Coding agents
Agentic Coding Best Practices for Multi-Agent Development
Four agentic coding best practices for teams running several agents: scoped ownership, context that survives handoffs, safe parallel runs, and review gates.
Coding agents
Agentic AI vs AI Agents: What’s the Difference?
Compare agentic AI and AI agents across goal scope, task decomposition, memory, and coordination, so you can tell which one your team is building.