A coordination pattern where several agents work on one goal at the same time, each in its own context, instead of one agent working it in sequence. Two shapes dominate: a fan-out where units are enumerated before any agent starts, and an orchestrator-worker setup where a lead decomposes and delegates at runtime.
Agentic Swarm Coding: How AI Agents Build Software Together
Learn what agentic swarm coding is, how several coding agents divide one codebase, what parallel runs cost in tokens, and when the pattern pays off.


Executive Summary
Agentic swarm coding runs several coding agents on one codebase at the same time, each with its own context, working toward a shared goal. It pays for work that splits into independent units with a checkable done state. On everything else, you pay for parallelism you cannot use, at roughly an order of magnitude more in token consumption.
Key takeaways
Agentic swarm coding assigns several coding agents concurrent tasks on one codebase, each working in its own context window.
Swarm coding pays on work that splits into independent units with a done state a build or a test can check.
Anthropic reports multi-agent systems use about 15x more tokens than chat interactions, measured on research tasks.
Anthropic also states most coding tasks contain fewer truly parallelizable tasks than research, which limits where swarms help.
BAND gives parallel coding agents a shared room, mention-based routing, and delivery tracking across separate sessions.
What Is Agentic Swarm Coding?
Anyone asking what agentic swarm coding is is asking about a setup rather than a category: several coding agents working at once on one codebase, each holding its own context, working toward a goal somebody else wrote down.
The definition of agentic swarm coding worth keeping is narrow. Agentic swarm coding is a development pattern in which several autonomous coding agents work concurrently on a single codebase. Each agent has its own context window, takes one unit of work, and opens its own change. A person or a lead agent decides how to divide the work and accepts what comes back.
The phrase is recent and informal. VentureBeat put it into circulation on 12 September 2025, quoting WEKA chief AI officer Val Bercovici calling it the successor to vibe coding, "where multiple agents in coordination are delivering very functional MVPs". No specification or standards body defines it. Faire's engineers write it as "swarm-coding," and others write "agent swarm" for much the same setup, so read any claim about swarm coding against what the writer actually ran.
How Coding Agent Swarms Divide and Execute Development Tasks
Work divides two ways, and the difference is who holds the plan.
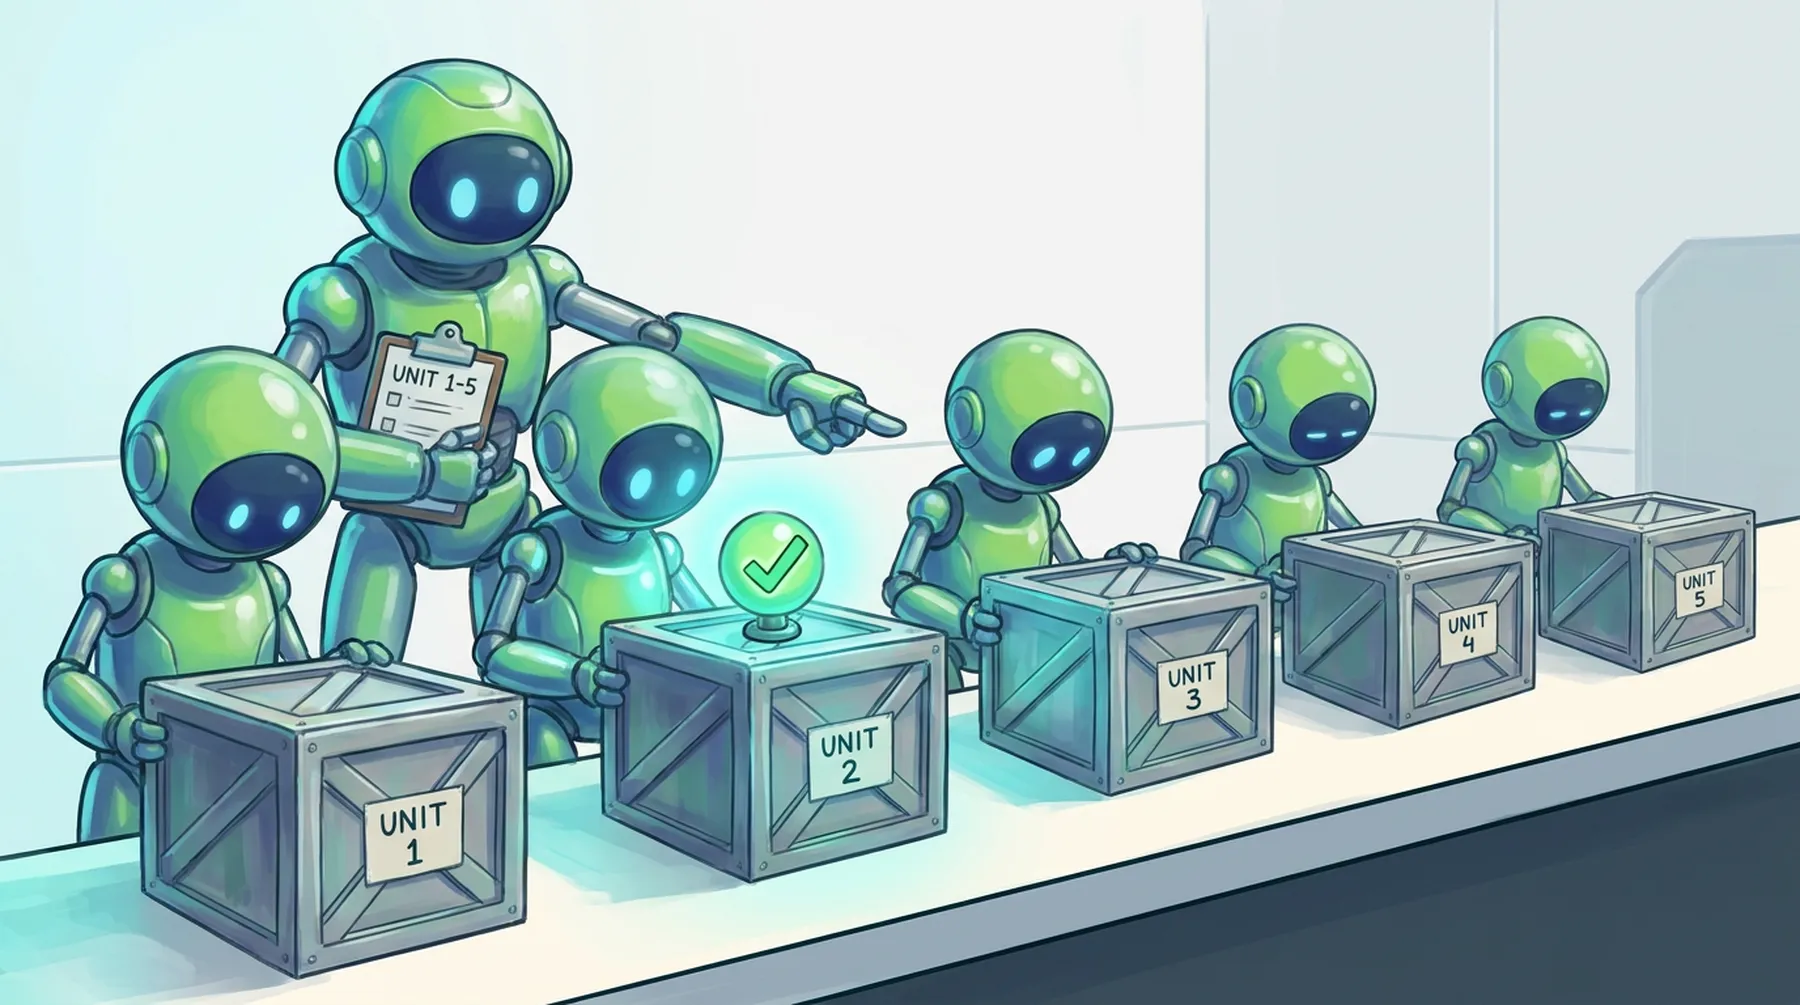
Fan-out from a task list. A person or a single agent enumerates the units first, and each unit goes to its own background agent, which opens its own change. Nothing coordinates at runtime, because the coordination happened when the list was written.
Most published enterprise applications of agentic swarm coding run this way, and Faire's is the one with numbers attached. Principal Engineer Luke Bjerring, writing on Faire's engineering publication The Craft on 19 August 2025, describes the iOS team migrating test mocks from SwiftyMocky to Mockolo: a prompt template with the protocol name as a variable, Cursor locating the areas still unmigrated, and each unit handed to a GitHub Copilot background agent running in parallel.
After just over a month with Copilot available, Faire reported that 18% of the engineering team had merged at least one Copilot pull request, that more than 500 such pull requests had merged, that pull-request volume among those engineers rose 25% on average, and that the average reported time saved was 39.6 minutes per pull request - Faire's methodology aligns with those figures. A "Copilot user" is anyone assigned to a merged Copilot-authored pull request; volume compares the four weeks before adoption against the four after, and the time saved is self-reported by the assignee from a fixed set of options, which is what that one decimal place rests on. Faire calls its adoption "in very early stages".
Orchestrator and workers. A lead agent decomposes the goal, delegates to workers, and merges the results. Anthropic's Research feature runs this shape, which its engineering team calls "an orchestrator-worker pattern, where a lead agent coordinates the process while delegating to specialized subagents that operate in parallel". The lead spins up three to five subagents at a time, each using three or more tools in parallel, which cut research time by up to 90% on complex queries. That is a research system, not a coding system, and the distinction decides the next section.
Agentic Swarm Coding vs Single-Agent Coding
Single-agent coding | Agentic swarm coding | |
|---|---|---|
Unit of work | One task, start to finish, in one session | One task pre-split into units, one per agent |
Context | One window holds the task and its history | Each agent holds its own, and nothing crosses unless someone moves it |
Cost of parallelism | One agent's token spend | About 15x a chat interaction, on Anthropic's research workloads |
Failure shape | The agent goes wrong in one visible place | Agents duplicate each other or leave gaps, and the gap appears at merge |
Human role | Review one change | Write the units, then review every change they produce |
The strongest published evidence for parallel agents comes from a research workload, and the same engineers say coding is a worse fit. Anthropic's June 2025 engineering post states that "some domains that require all agents to share the same context or involve many dependencies between agents are not a good fit for multi-agent systems today. For instance, most coding tasks involve fewer truly parallelizable tasks than research, and LLM agents are not yet great at coordinating and delegating to other agents in real time."
That is the same team reporting that a multi-agent system with Claude Opus 4 leading Claude Sonnet 4 subagents beat single-agent Claude Opus 4 by 90.2% on their internal research eval. The dependency structure is why the result doesn't carry over to your repository: two agents researching different companies never collide, while two agents touching the same module do.
The post names where the pattern pays: heavy parallelization, information exceeding a single context window, and interfaces to many complex tools. A mock migration across hundreds of test files meets that description. One feature threaded through four layers of a service does not.
The Coordination Challenge: Context, Dependencies, and Agent Handoffs
Three failures recur across both accounts, and none is a model quality problem. The first is duplicated and gapped work: Anthropic found that "without detailed task descriptions, agents duplicate work, leave gaps, or fail to find necessary information", and gives a case where one subagent investigated the 2021 automotive chip crisis while two others both worked current supply chains. The second is blocked coordination, because the lead runs its subagents synchronously, so "the lead agent can't steer subagents, subagents can't coordinate, and the entire system can be blocked while waiting for a single subagent to finish searching". The third is lost state, where nothing outside the agents records which units are in flight and the orchestrator reassigns work already underway. Faire kept that record in the ticketing system its engineers already used.
As requirements rather than products, the mitigations are a task description precise enough that two agents cannot read it the same way, a record of in-flight work that lives outside every agent, and a shared place for results to land instead of passing them through a chain of messages. Anthropic's version of the last has subagents write output to a filesystem and pass lightweight references back, minimizing what the post calls the "game of telephone". Parallel sessions put that load back on a person, who becomes the team's memory and message router when no shared record exists, as in the coordination problem in multi-agent coding. Copies of one model also share priors and blind spots, so a larger swarm buys throughput rather than a second opinion, the separate argument in multi-agent coordination failure.
Orchestrating Agentic Coding Swarms with BAND
Once several coding agents work on one repository from separate sessions, teams need a shared place to see who owns which unit, whether a handoff arrived, and what is still running. BAND provides that layer, and each mechanism answers one of the three failures above.
Agents from different sessions and frameworks join one room, so the plan and the handoffs sit on a board a person can read rather than in five terminals nobody is watching. That room also records in-flight work, held outside any single agent's context. Mention-based routing decides who acts, because an agent receives and processes a message only when addressed, which structurally prevents two agents from picking up the same unit. Delivery tracking gives every handoff a state, moving through delivered, processing, and then processed or failed with attempt history behind it, so a unit that died reads as dead instead of as finished. BAND's loop engineering post describes that shape for coding agents.
One limit is worth stating plainly. None of this makes a codebase more parallelizable. Where work doesn't split into units with a checkable done state, coordination infrastructure buys an accurate record of agents getting in each other's way. The split decision comes first. When several coding agents already run on one repository, and nobody can say which unit is in flight, that gap is what the BAND platform covers.
Frequently Asked Questions About Agentic Swarm Coding
The constraint is not agent count. It is how many units are genuinely independent, and how many changes a reviewer can absorb. Two units touching the same module produce a merge conflict rather than throughput. Anthropic's published scaling rules reach more than ten subagents, but were written for research tasks.
Two classes have production accounts behind them. Mechanical migrations with a verifiable done state, such as Faire's iOS test-mock migration, where a compile and a test run decide whether a unit is finished. And cleanup work: expired feature flags, dead code, and deprecated call sites.
Yes. Anthropic reports agents typically use about 4x more tokens than chat interactions, and multi-agent systems about 15x more. Both are Anthropic's own figures from building its research system, not coding benchmarks, so read them as an order of magnitude. Faire published adoption figures for its coding swarm but no token cost.
Isolation handles collisions rather than preventing them. A background agent works in its own ephemeral environment, checks out the repository, and opens its own pull request, so two agents editing one file surface as a merge conflict instead of corrupting each other mid-edit. Preventing it earlier means assigning module ownership per unit when you write the list.
Sign Up For The Band
A short and to the point summary of what we've been up to, delivered once a month to your inbox.
By submitting this form, I agree to be contacted by Band and receive occasional offers & product updates via phone or email, in line with Band’s Privacy Policy.
Coding agents
Best Platforms for Monitoring AI Coding Agents in 2026
Five criteria for monitoring AI coding agents, compared across native telemetry, APM, engineering intelligence, and coordination layers.
Coding agents
What is agentic coding? How the agent loop works
Learn what agentic coding is, how the plan, act, and verify loop closes, and what separates it from the AI code completion your team already uses.
Coding agents
Agentic Coding Workflows: How AI Agents Work Together
An agentic coding workflow moves one ticket through intake, plan, implement, verify, and review. Here are the stages, the handoffs, and where a person decides.