Only for fuzzy recall over large text, such as finding past supplier emails that resemble a new dispute. Facts with a known subject, like a VAT ID, fit keyed records, where exact lookups and superseding are simpler. Nothing stops a system from using both.
AI Agent Memory: How to Manage Context Across Multiple Agents
AI agent memory is the information an agent carries beyond one model call: the working context for the current step, plus stored facts, past events, and rules it can read back later.


Key takeaways about AI agent memory
AI agent memory includes the working context of the current model call plus long-term stores an agent reads from and writes to between calls.
The CoALA framework splits long-term agent memory into episodic, semantic, and procedural types, and any of those types can be shared through a read scope.
Among AI agent memory management techniques, write policy decides which facts get stored, when an agent stores them, and how new values supersede old ones.
Giving every shared memory record one subject and one designated writer limits stale reads and conflicting writes when several agents work on the same process.
BAND scopes each stored agent memory to one agent, one subject, or an entire organization, and prevents memories from crossing organization boundaries.
What Is AI Agent Memory and How Does It Work?
AI agent memory is the state an agent keeps outside the model's weights so later steps can use what earlier ones learned. The context window is working memory, rebuilt on every call. Anything that must outlive the call sits in a store the agent reads and writes to, no matter how large the window gets.
I find CoALA the clearest model of this loop. In Cognitive Architectures for Language Agents (2023, revised 2024), Theodore Sumers, Shunyu Yao, Karthik Narasimhan, and Thomas Griffiths sort internal actions by direction: retrieval reads long-term memory into working memory, and learning writes back. Once the write is an action the agent chooses, you can design when it happens.
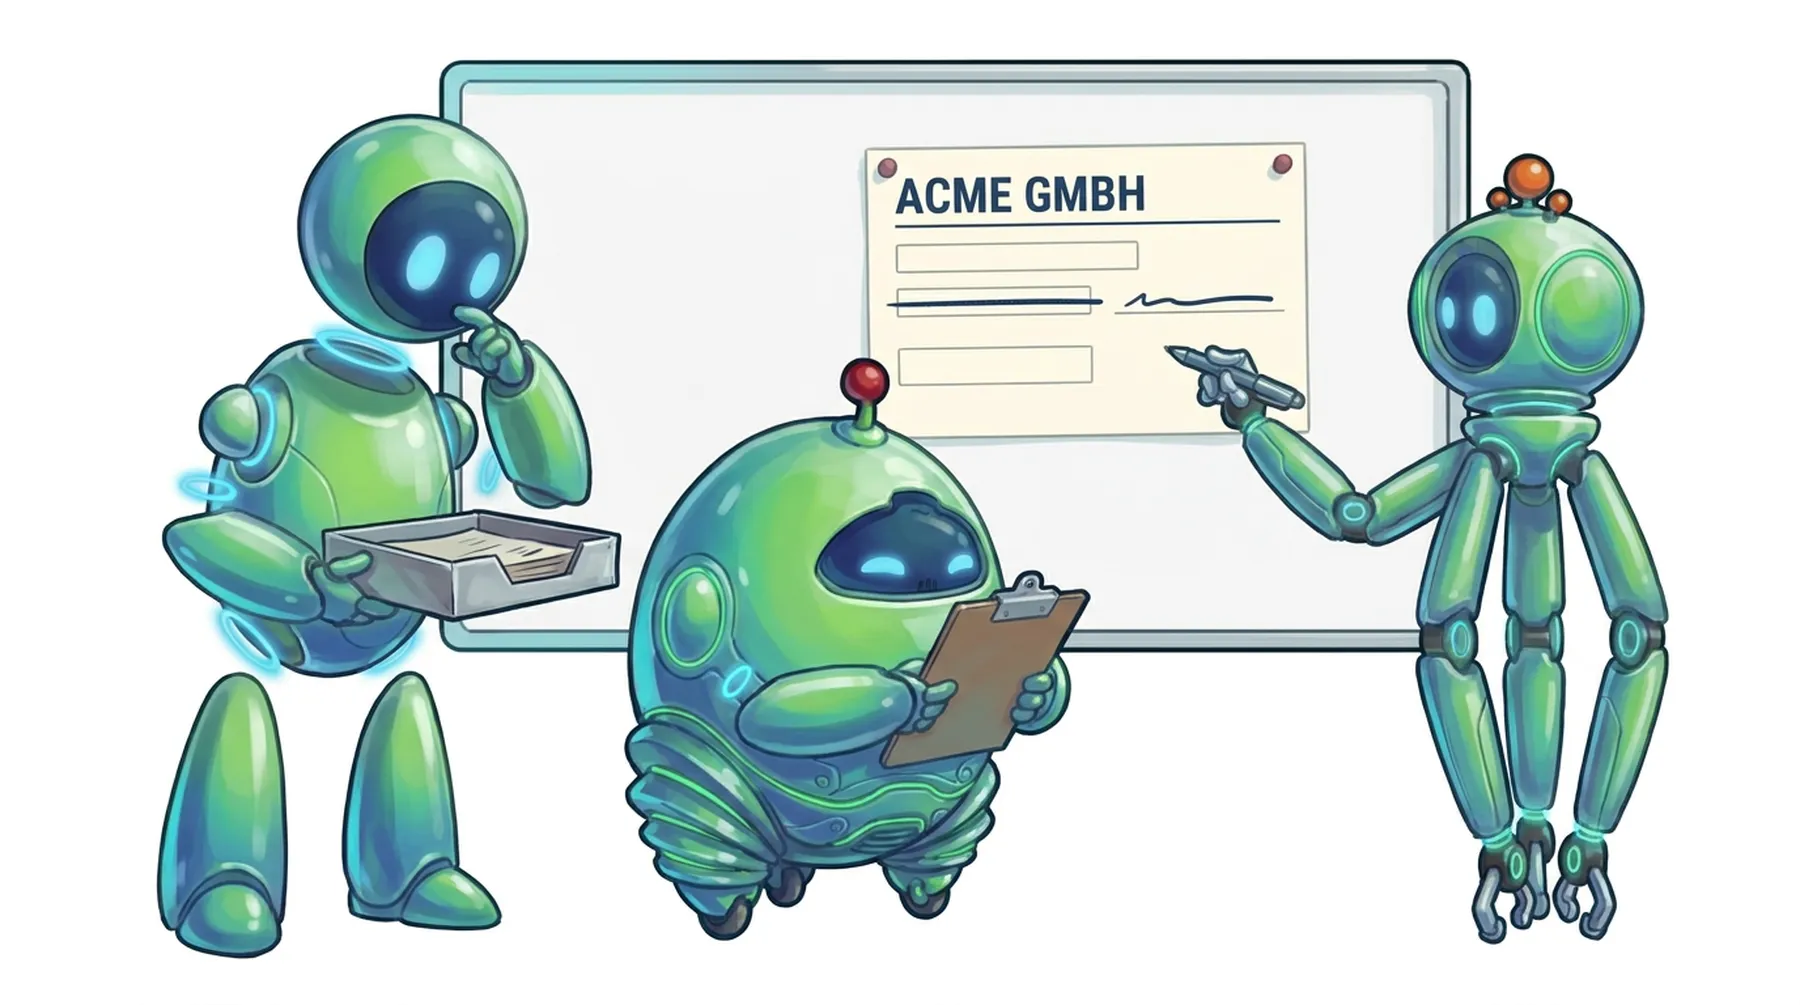
AI agent memory management is that design: what gets written, by which agent, and when it is read. The intake agent writes "legal entity verified" on day 1 so the compliance agent can retrieve it on day 4. The store is a component of agentic architecture, and the policy determines whether the compliance agent finds the record.
AI Agent Memory Management Techniques and Architectures
AI agent memory management techniques govern both writes and reads, but write policy comes first: a read can only return what an earlier write left behind.
Techniques for writing, compacting, and expiring records
Write when an agent decides something, such as "sanctions screening passed", and leave routine turns in the transcript. Summarize finished steps before the window fills, and give each record an expiry tied to its workflow.
Supersede handles facts that change. When Acme sends new bank details on day 6, overwriting looks tidy until an auditor asks which account the day 5 draft used. Marking the old record superseded and writing a new one keeps both.
Per-agent, shared, and hybrid memory stores
Architecture | How agents use it | What breaks first |
|---|---|---|
Per-agent | Each agent keeps its own store | Copies drift; contracts miss the bank change |
Shared | All agents use the same records | Conflicting writes and bloated contexts |
Hybrid | Private scratch plus scoped shared records | Scope rules someone must maintain |
A hybrid approach is a practical starting point, since drift and context flooding both get harder to undo later. Across applications, the same split shows up as the state plane in a mesh.
Challenges of Managing Memory and Context Across Multiple AI Agents
AI agent memory context management means choosing which slice of shared memory enters each agent's prompt. With three agents on one supplier, four failures appear even when every agent behaves correctly:
The contracts agent drafts payment instructions on day 9 from bank details loaded on day 3, and nothing flags the stale read.
Intake records net-60 terms from an email while contracts records net-30 from the master agreement. With no field owner, the last write wins.
Every agent loads every supplier fact. A larger window postpones the overflow while raising cost per call and burying the record that mattered.
The compliance agent's sanctions note reaches the agent drafting supplier email, because the store had one scope. That leak tends to surface in an audit.
Managing Agent Memory Across Sessions and Workflows with BAND
Memory for several agents is a write policy, a read policy, and a scope on every record. Sessions still end. When an agent restarts or reconnects, BAND’s context endpoint returns the messages it sent or was mentioned in, along with its own events, such as tool calls, thoughts, and errors, and the SDK uses that context to rebuild its history.
Open tasks, like a compliance question unresolved on day 11, can remain visible in BAND Desktop with ownership and status that outlive any single agent session. BAND doesn't decide what an agent remembers, act as a vector database, or replace a framework’s short-term state, such as a LangGraph checkpointer.
The video on work that outlives sessions shows the obligation side, and long-running multi-agent workflows show rooms across a full lifecycle. The endpoints live in the BAND Agent API.
Book a demo to map where each fact in your own agent workflow should live.
FAQs about AI agent memory
No. Consumer assistant memory features generally carry user-specific context across conversations within one product. Agent memory, by contrast, is infrastructure you design for agents you run, with explicit rules for writes, reads, scope, and expiry.
Managed memory is a store a platform runs for you. The platform persists, scopes, and isolates records, while the agent still decides what to write. You trade infrastructure work for some control over how memory is stored and managed, so check retention, portability, and export options before committing.
RAG retrieves from a corpus the agent did not write, such as policies or product documentation. Memory holds what agents recorded while working: decisions, events, and corrected facts. The line blurs when an agent's own summaries get indexed like documents, which is where agentic RAG architecture picks up.
You can't rule it out. The OWASP AI Agent Security Cheat Sheet lists memory poisoning as a risk and recommends validating data before storing it, isolating memory between users and sessions, and setting expiration and size limits. Recording each record's writer at least shows where a bad memory came from.
Sign Up For The Band
A short and to the point summary of what we've been up to, delivered once a month to your inbox.
By submitting this form, I agree to be contacted by Band and receive occasional offers & product updates via phone or email, in line with Band’s Privacy Policy.
Coding agents
Personal AI Agents Explained: Examples, Protocols, and Use Cases
Learn what a personal AI agent is, 10 ways developers use one, which protocol each connection needs, and how to test a first agent-to-agent handoff.
Coding agents
AI Agent Interoperability: Connecting Agents Across Frameworks
Why agents built on different frameworks cannot talk by default, what A2A and MCP standardize in 2026, and the runtime layer teams still have to add.
Coding agents
AI Agent Task Delegation: How to Coordinate Multiple Agents
Learn how AI agent task delegation and coordination work, from scoping a subtask to verifying its result, plus the patterns and practices that keep it safe.